Back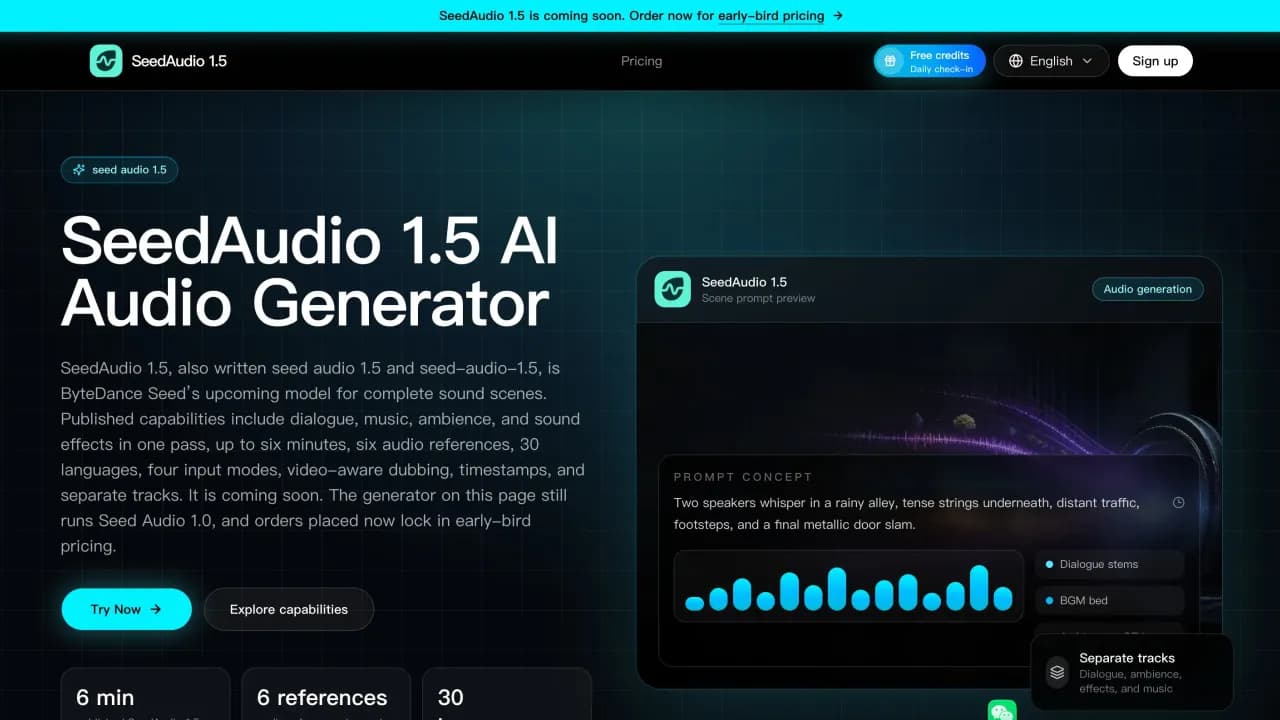


Seed Audio 1.5
Generate dialogue, music, ambience, and effects as one audio scene
- Audio & Voice
- Web
SeedAudio 1.5 is an upcoming audio-generation model that creates dialogue, music, ambience, and sound effects together from a scene brief, addressing the work of assembling layered audio separately. It is aimed at creators producing video dubbing, podcasts, audiobooks, game scenes, ads, and other narrated or sound-designed content.
- Combine dialogue, ambience, foley, and music in a single generation.
- Use text, text plus audio, text plus video, or combined audio-and-video inputs.
- Guide voices with references; published specifications list up to six audio references.
- Generate up to six minutes with dialogue, ambience, effects, and music as separate tracks.
Published specifications describe 30 languages with regional variants, timestamp control, and video-aware dubbing. SeedAudio 1.5 is not live yet; the page’s current online generator runs Seed Audio 1.0.
Also launched this week
LaunchListGet AI and superintelligence products featured in weekly launches
HiAPIGenerate images, video, audio, and text through one API
Better LaunchPost your product and get discovered fast by builders and early adopters
EmailVerify.ioBulk email verification, list cleaning, and API validation
LayerBackConvert diagram images into editable files